

This feature is provided by ayaka-notes/ayakaleaf-pro and is available from v6.3.0. We welcome your feedback if you encounter any problems.
AI assistant and LaTeX error assistant
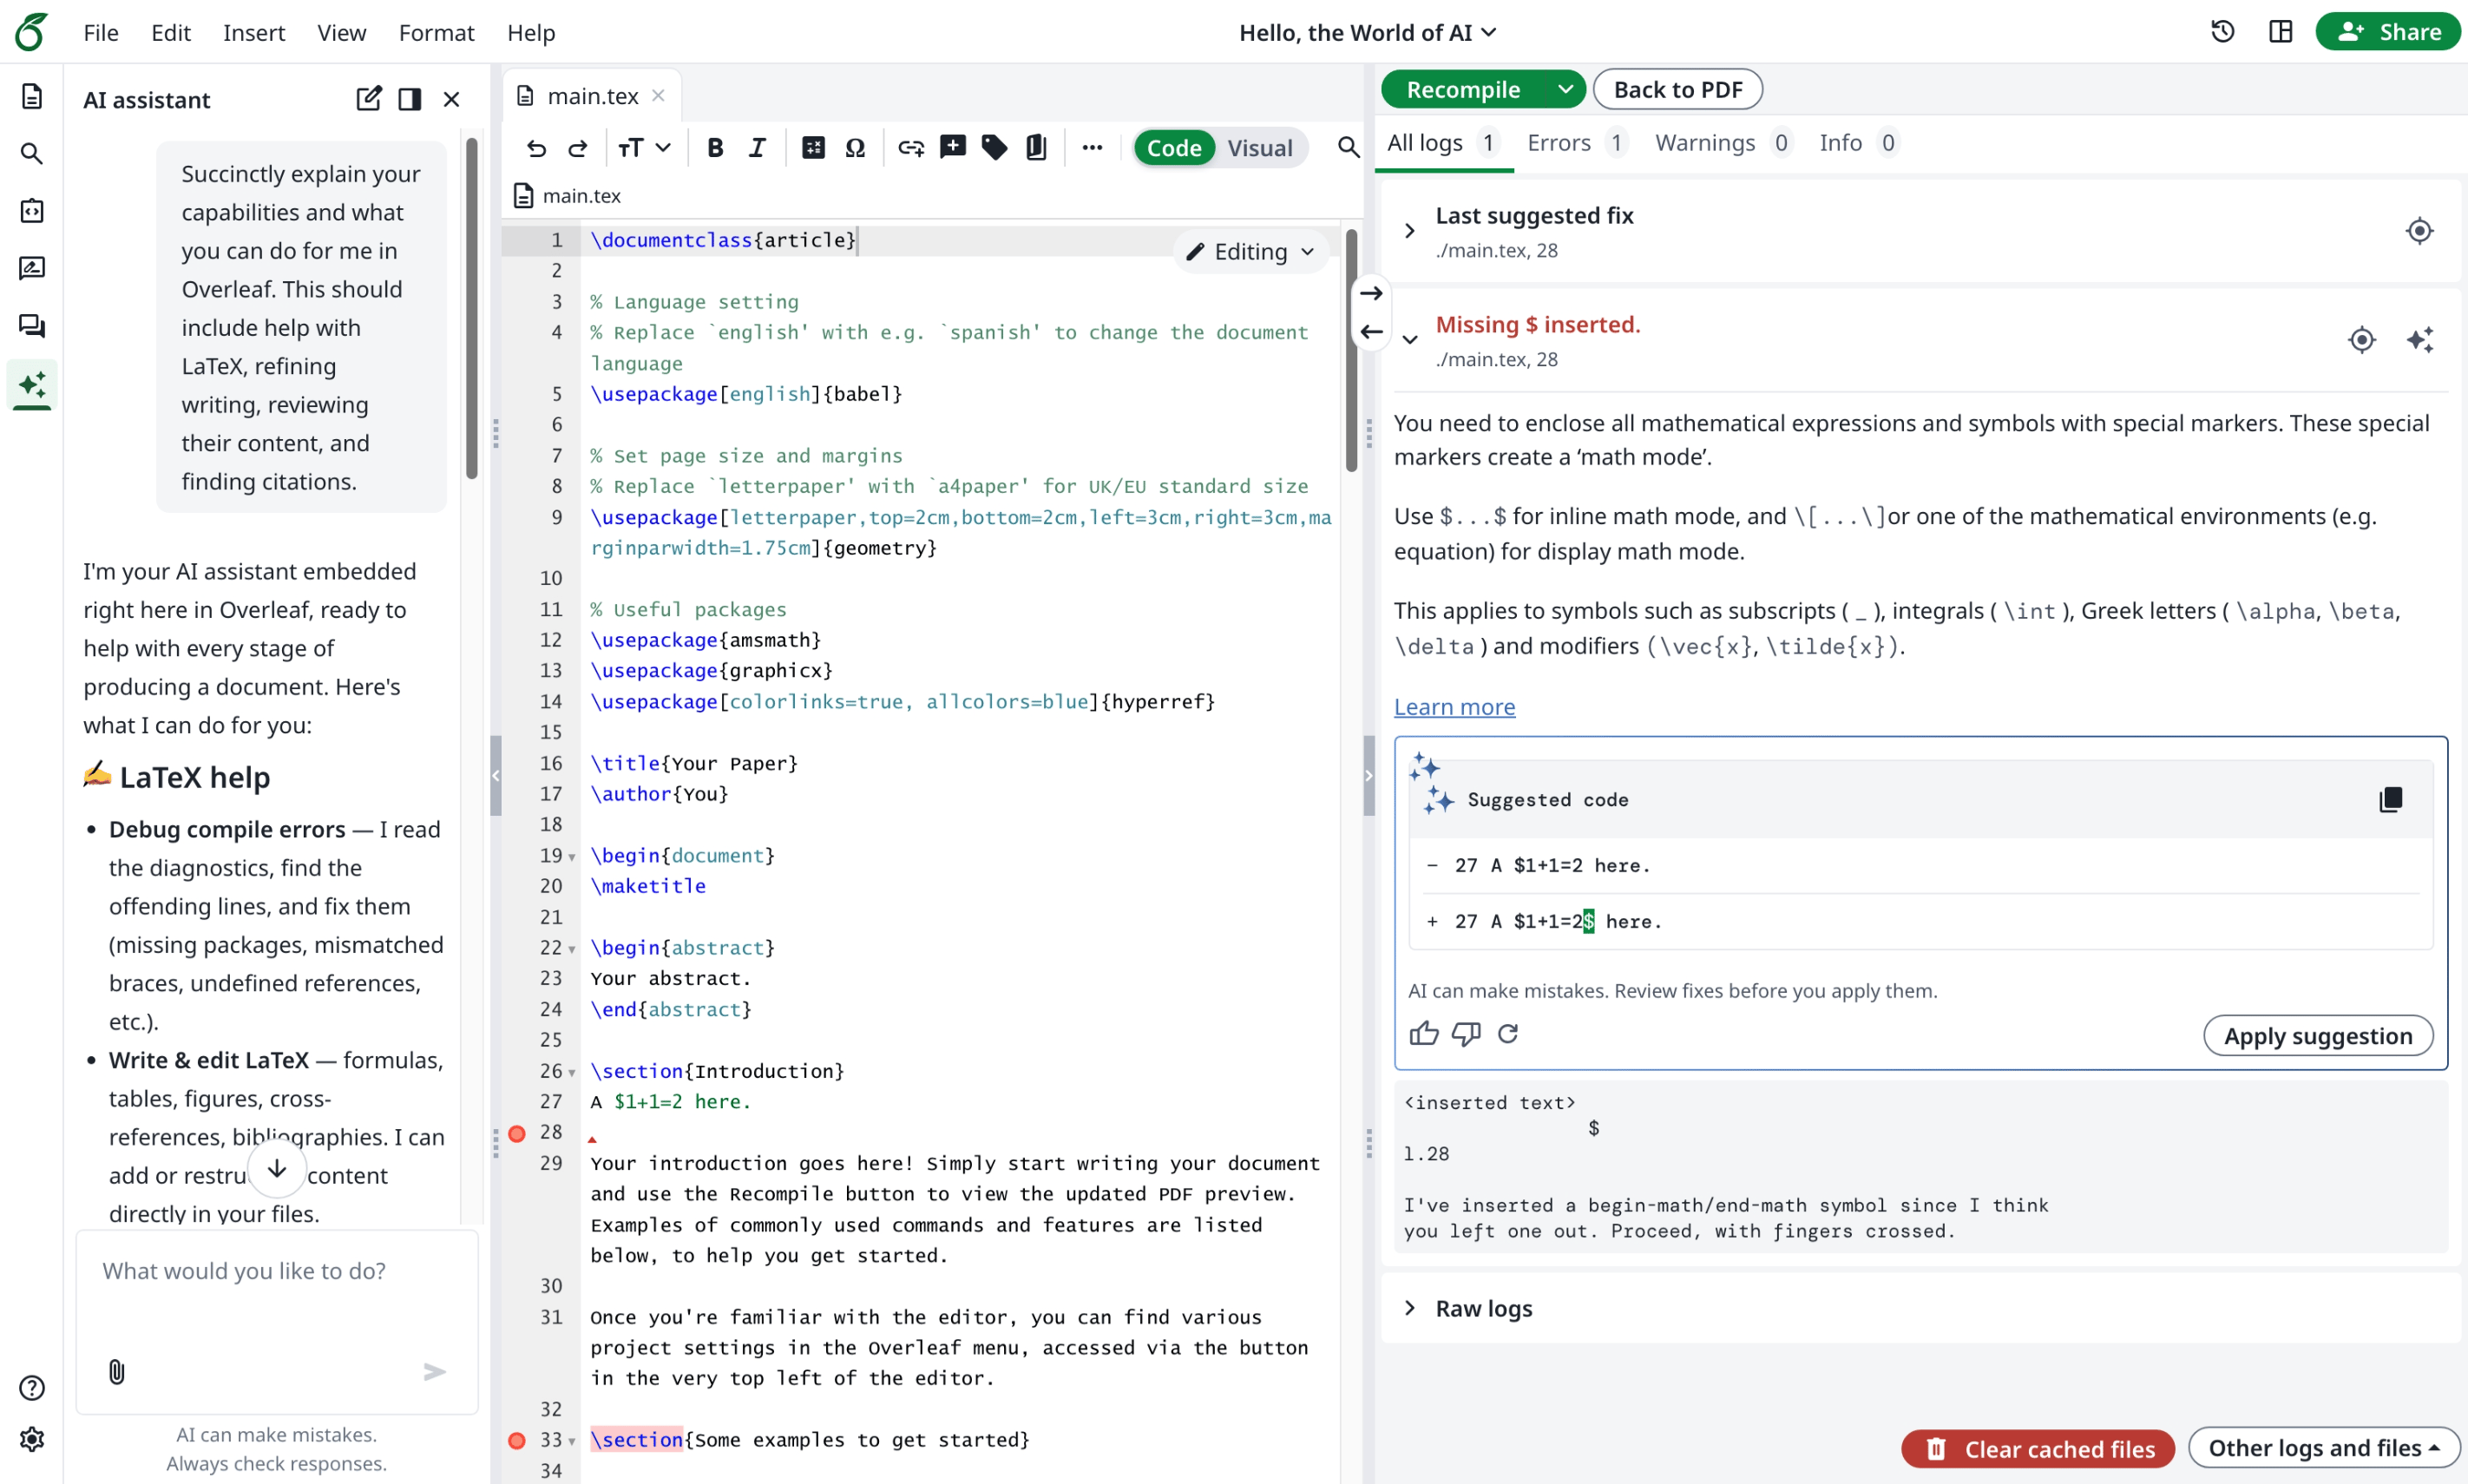
Ayakaleaf Pro brings AI features into the editor in 2 ways.- The AI Assistant can use your project documents and current selection as context to answer questions and suggest edits for you to review.
- The Error Assistant proposes a targeted fix when you select a LaTeX compilation error.
Toolkit configuration
Add the following toconfig/variables.env in your Toolkit deployment, replacing the example URL, key, and model with values from your provider:
The quality of AI suggestions depends on the model you choose. If you already have a Codex or ChatGPT subscription, you can connect it via CLIProxyAPI’s OpenAI-compatible endpoint.
AI_BASE_URL is the OpenAI-compatible API base URL, including the provider’s version prefix where required. Do not append /chat/completions since we will append this internally (/responses with AI_API_MODE=responses, see below). The gateway and model must support streaming chat completions and function tools. Both features send document context to this gateway; chat can also send uploaded images and PDF files when using a model that accepts them.
Toolkit forwards config/variables.env into the application container. Keep the variable names shown here; do not add an OVERLEAF_ prefix. From the Toolkit directory, recreate the application container after changing these variables:
Gateway settings
For image uploads, set
AI_IMAGE_MODEL to a model that accepts image input and supports the tools used by chat. Any chat request whose history contains an image attachment uses this model, including later messages in that conversation. Without this setting, image requests use the normal chat model, which must itself support images. LaTeX error suggestions continue to use AI_MODEL.
PDF attachments are introduced from v6.4.0 and later. Users can attach PDF files of up to 2 MB, like images. The chat sends each PDF file as it is, as a Chat Completions file part (an input_file with AI_API_MODE=responses), so the gateway and model must accept PDF input: OpenAI’s vision models do, while many self-hosted gateways, such as vLLM, accept images but refuse PDF files. Set AI_PDF_MODEL to a model that reads PDF files; any chat whose history contains a PDF file uses it, including later messages and any images in that conversation, so it should accept images too. Without this setting, PDF chats use AI_MODEL. When the model refuses a PDF file, the chat tells the user to ask the administrator to set AI_PDF_MODEL.
The OpenAI Responses API is supported from v6.3.3 and later. Set AI_API_MODE=responses for models that take function tools only there: on Chat Completions, OpenAI’s newer reasoning models refuse every chat request with Function tools with reasoning_effort are not supported for <model> in /v1/chat/completions. The gateway must implement /responses; OpenAI does, many other OpenAI-compatible gateways do not. Both assistants, image and PDF attachments and the token quota work as with Chat Completions. The provider keeps each response, as the Responses API does by default (OpenAI keeps them for at least 30 days), and the later requests of a chat refer to the earlier answers and tool calls by their IDs instead of sending them again.
For example, to enable an image model and a weekly AI allowance:
User access and consent
Instance availability and user permission are separate.AI_ENABLED and the gateway configuration control instance availability. A signed-in user must also pass the existing account check: aiFeatures.enabled must not be false. This existing database field controls both chat and LaTeX error suggestions. When it is unset, AI features are enabled for the user.
AI_TOKEN_QUOTA is a limit applied equally to each permitted user; the current module does not provide an individual numeric limit per account.
In Admin → Manage Users, click the user’s name, open the Features tab and click the pencil icon. Turn Enabled under AI features on or off and click Save: this updates aiFeatures.enabled. The server checks current permissions on new AI requests, including requests from an already open editor. A user without permission still sees the AI assistant in the editor, but cannot send messages.
Usage and reset
The AI usage row on the Features tab shows the current period’s usage and limit, with a Reset button. Usage is read when the page opens; it is not continuously refreshed. Reload the page after a chat or error suggestion finishes to see the latest count. Reset takes effect immediately and clears only that user’s current period counter, then updates the displayed usage. It does not need the pencil icon or Save. It is greyed out when the usage is 0 and on your own account.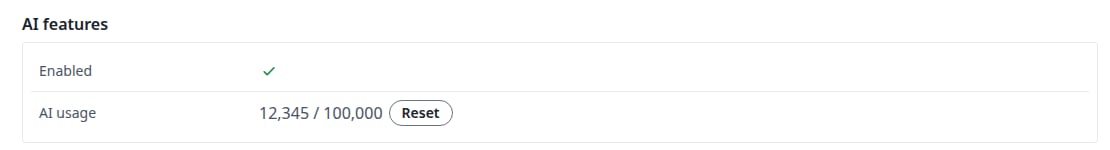
A user's AI permission and usage
AI_TOKEN_QUOTA; error suggestions have no separate request-count limit. Resetting the counter does not change permission, consent, the configured limit, or the provider’s own billing records. Counters use UTC period keys and expire after 40 days; retaining Redis data preserves current usage across application restarts.
Optional search services
Web search uses a Tavily-compatible API. It is available when a search API key is configured. These settings are independent of the AI gateway:
For example:
searchDocumentation tool and accepts JSON or SSE responses. This is an MCP client for documentation search. To let AI clients outside Ayakaleaf work on a project, see MCP Server.
Reading web pages is introduced from v6.4.0 and later. The chat can read a page by its URL, such as a link the user gives or a search result. It fetches the page through the linked URL proxy, the same service that fetches files from external URLs, so the network restrictions described in External URL apply to it too. No further setting is needed.
Search queries go to the configured search service. Search results can then be included in requests to the AI gateway. The chat’s Tools menu lets users enable or disable Web and Documentation for their requests; a tool must also be configured on the server to be available to the model.
Q&A
The AI assistant does not appear in the editor
The AI assistant does not appear in the editor
Answer: The AI assistant appears in the editor’s left rail only when
AI_ENABLED=true and AI_BASE_URL, AI_API_KEY and AI_MODEL are all set. If one of them is missing, the AI assistant is hidden for every user.After changing config/variables.env, recreate the container with bin/up -d. Refreshing the browser alone does not apply new variables. The Enabled switch under AI features in the admin panel does not show or hide the AI assistant; it only decides whether the user can send messages.I send a message, but the AI assistant does not reply
I send a message, but the AI assistant does not reply
Answer: First, check that the user has accepted the AI consent card shown in the AI assistant. Messages cannot be sent before that.Then look for errors in the web service log:
If your provider’s dashboard shows no usage, the request did not reach the provider. Common causes are:
AI_BASE_URLis wrong, for example a missing or extra/v1, or/chat/completionsor/responsesappended to it.- The server cannot reach the gateway. If outgoing traffic must go through a proxy, set
AI_PROXY_URL. AI_MODELis not a model ID that the gateway knows.
Function tools with reasoning_effort are not supported and suggests /v1/responses, set AI_API_MODE=responses.Is the chat history kept?
Is the chat history kept?
Answer: No. A chat is only kept in the open browser tab. Refreshing or closing the page clears it, and Start new chat replaces the current chat. There is no list of earlier chats, and each project shows one chat at a time.